NVIDIA Hopper 2022 to 2024
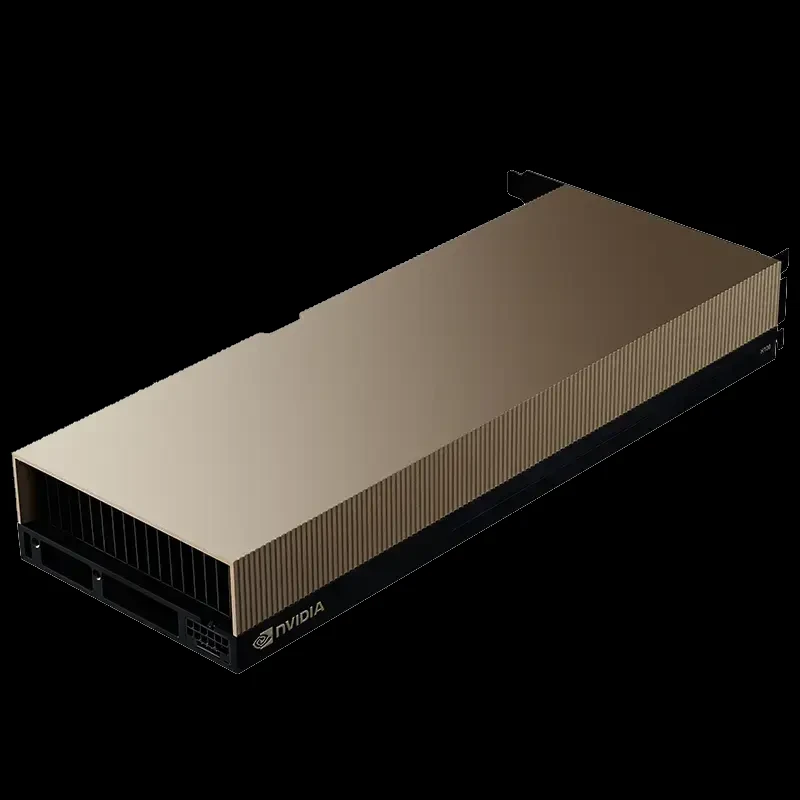
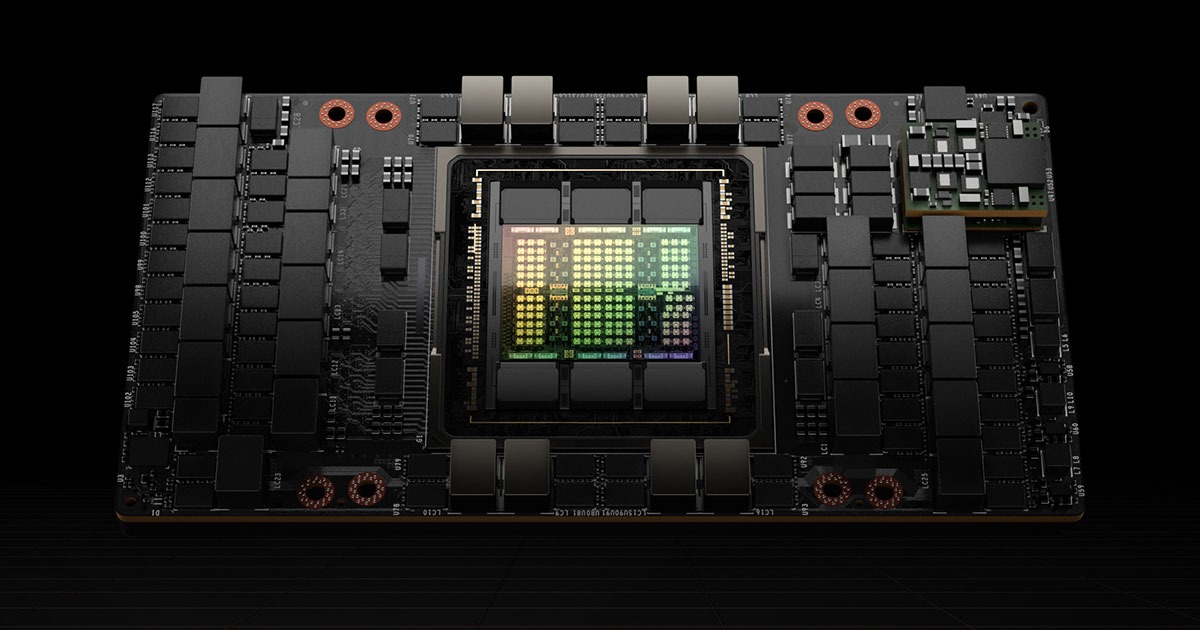
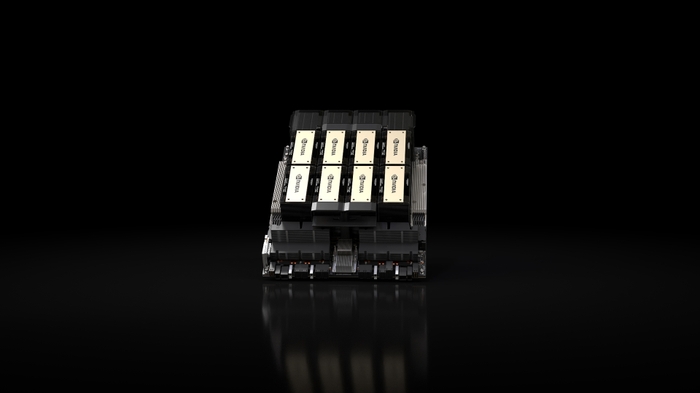
NVIDIA Hopper powered the first wave of large language model training and inference at scale. The H100 and H200 introduced fourth-generation Tensor Cores with the FP8 Transformer Engine, HBM3 and HBM3e memory with up to 4.8 TB/s of bandwidth, and fourth-generation NVLink at 900 GB/s. Hopper GPUs remain the workhorse of many AI clusters and are available in PCIe NVL and SXM form factors.
- Fourth-generation Tensor Cores with FP8 Transformer Engine
- HBM3 (H100) and HBM3e (H200) memory
- NVLink 4 at 900 GB/s and NVLink bridges for PCIe pairs
- Multi-Instance GPU with up to 7 instances
- Confidential computing